TimeSeries Code for Critical Systems
A Time-series R&D Agent for Critical Infrastructures, Facilities, and Equipments
Our research on Critical AIOps explores how local AI can support time-series analysis in the operation and maintenance of critical systems. We want to keep critical systems working, helping them perform their intended functions reliably. Planned maintenance, a safe shutdown and recovery can all serve that goal. We are developing TimeSeries Code, an R&D agent that helps users develop, test and improve Time Series Agents for their own systems. Model inference, tool execution and validation take place in the user’s local environment, using the data and knowledge the user has authorized. The work continues as users gain experience with the deployed agents.
Project materials
Presentation slides (PDF)
The architecture and an end-to-end development example. 25 bilingual slides.
Both videos use the bilingual slides, with captions in the spoken language and an authorized AI-generated version of the presenter’s voice.
Research motivation
We use critical systems to refer to critical infrastructure and major industrial and scientific equipment and facilities. These systems continuously produce numerical observations from physical sensors and operational telemetry. A time series records measurements in time order. Temperature, vibration, power and performance measurements record how a system behaves and changes. Our research on time-series intelligence asks how these observations can help us perceive system state, reason about what is happening, predict changes and support operational decisions. Data centers, generating units, aircraft, manufacturing equipment and scientific facilities provide important settings for this work.
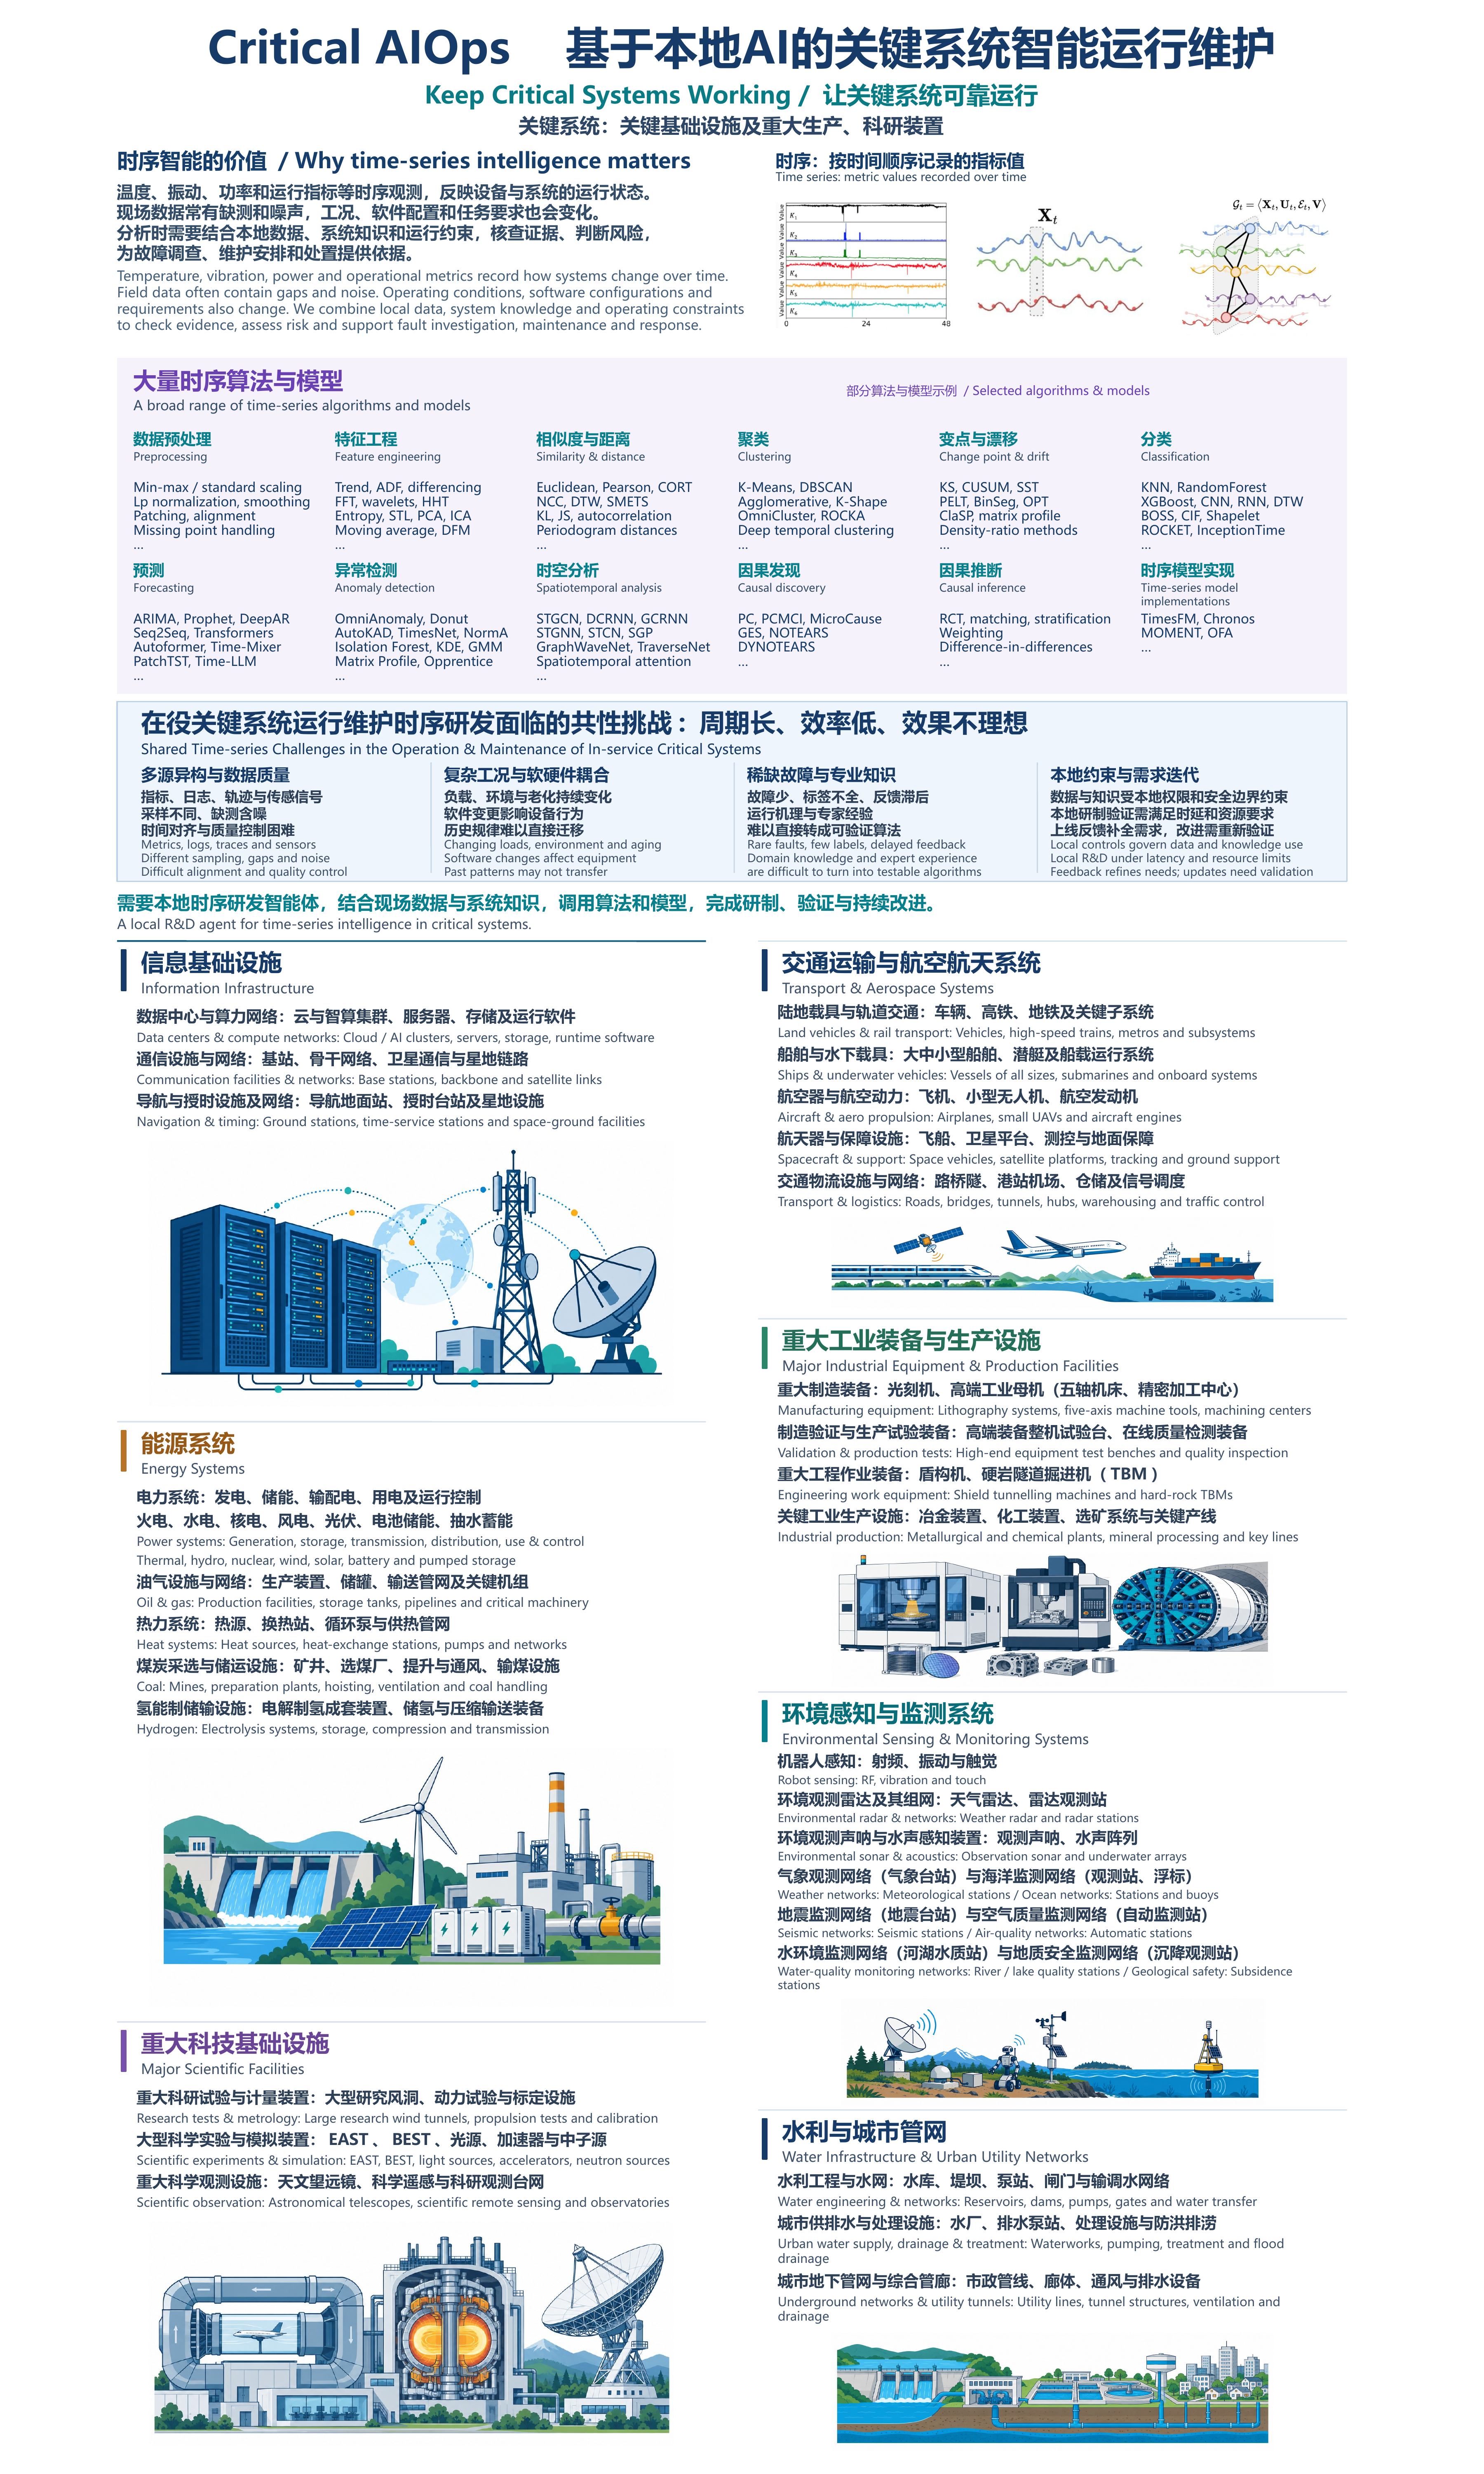
There is already a broad range of time-series algorithms and models. Methods cover preprocessing, feature engineering, similarity and distance, clustering, change points and drift, classification, forecasting, anomaly detection, spatiotemporal analysis, causal discovery and causal inference, alongside time-series model implementations. The poster gives representative examples, including ARIMA, OmniAnomaly and TimesFM. They illustrate the methods available to a developer, rather than a claim that every listed method has been integrated and validated in our system. Putting a method into operation requires choosing an appropriate implementation, connecting it to the local data and testing it under the conditions in which it will be used.
A method that works well on development and evaluation datasets can perform poorly in a user’s operating environment. Equipment, workloads, control settings and operating practices vary across installations. Even two installations of the same type of equipment may produce different patterns. The data used to develop a method may therefore differ substantially from the observations it encounters in operation.
Local data often contain gaps and noise. Sensors can drift, sampling rates can differ and timestamps may be misaligned. A large archive of routine operation may contain very few labeled failures. Interpretation also depends on information outside the measurements: a generating unit’s rising temperature, for example, could follow a load increase or indicate degradation. Knowledge about the equipment, its configuration and earlier maintenance may be incomplete or out of date.
Conditions continue to change after deployment. Maintenance, aging and software updates can alter the patterns that an algorithm relies on. A detector may start producing excessive reports or miss a change that matters. Users also refine their requirements after seeing the results. A useful method needs repeated checking against these changes, with evidence that the operating team can examine.
Developing such a method involves data preparation and domain knowledge as well as algorithm implementation, testing and deployment. The work must respect local limits on latency, computing resources, privacy and safety. In many of the environments we target, data and execution records cannot leave the user’s environment. We therefore focus on development and validation that can take place locally. Local can mean a user-controlled workstation, server or private cloud. Skill and workflow improvements can proceed there even when model-training resources are unavailable.
TimeSeries Code is our design for supporting this work. It brings the available data and knowledge together with explicit goals and constraints, develops alternatives, and tests them before delivery. When operation reveals a missing requirement or a failed assumption, the agent can help carry out another development cycle.
Development and local operation
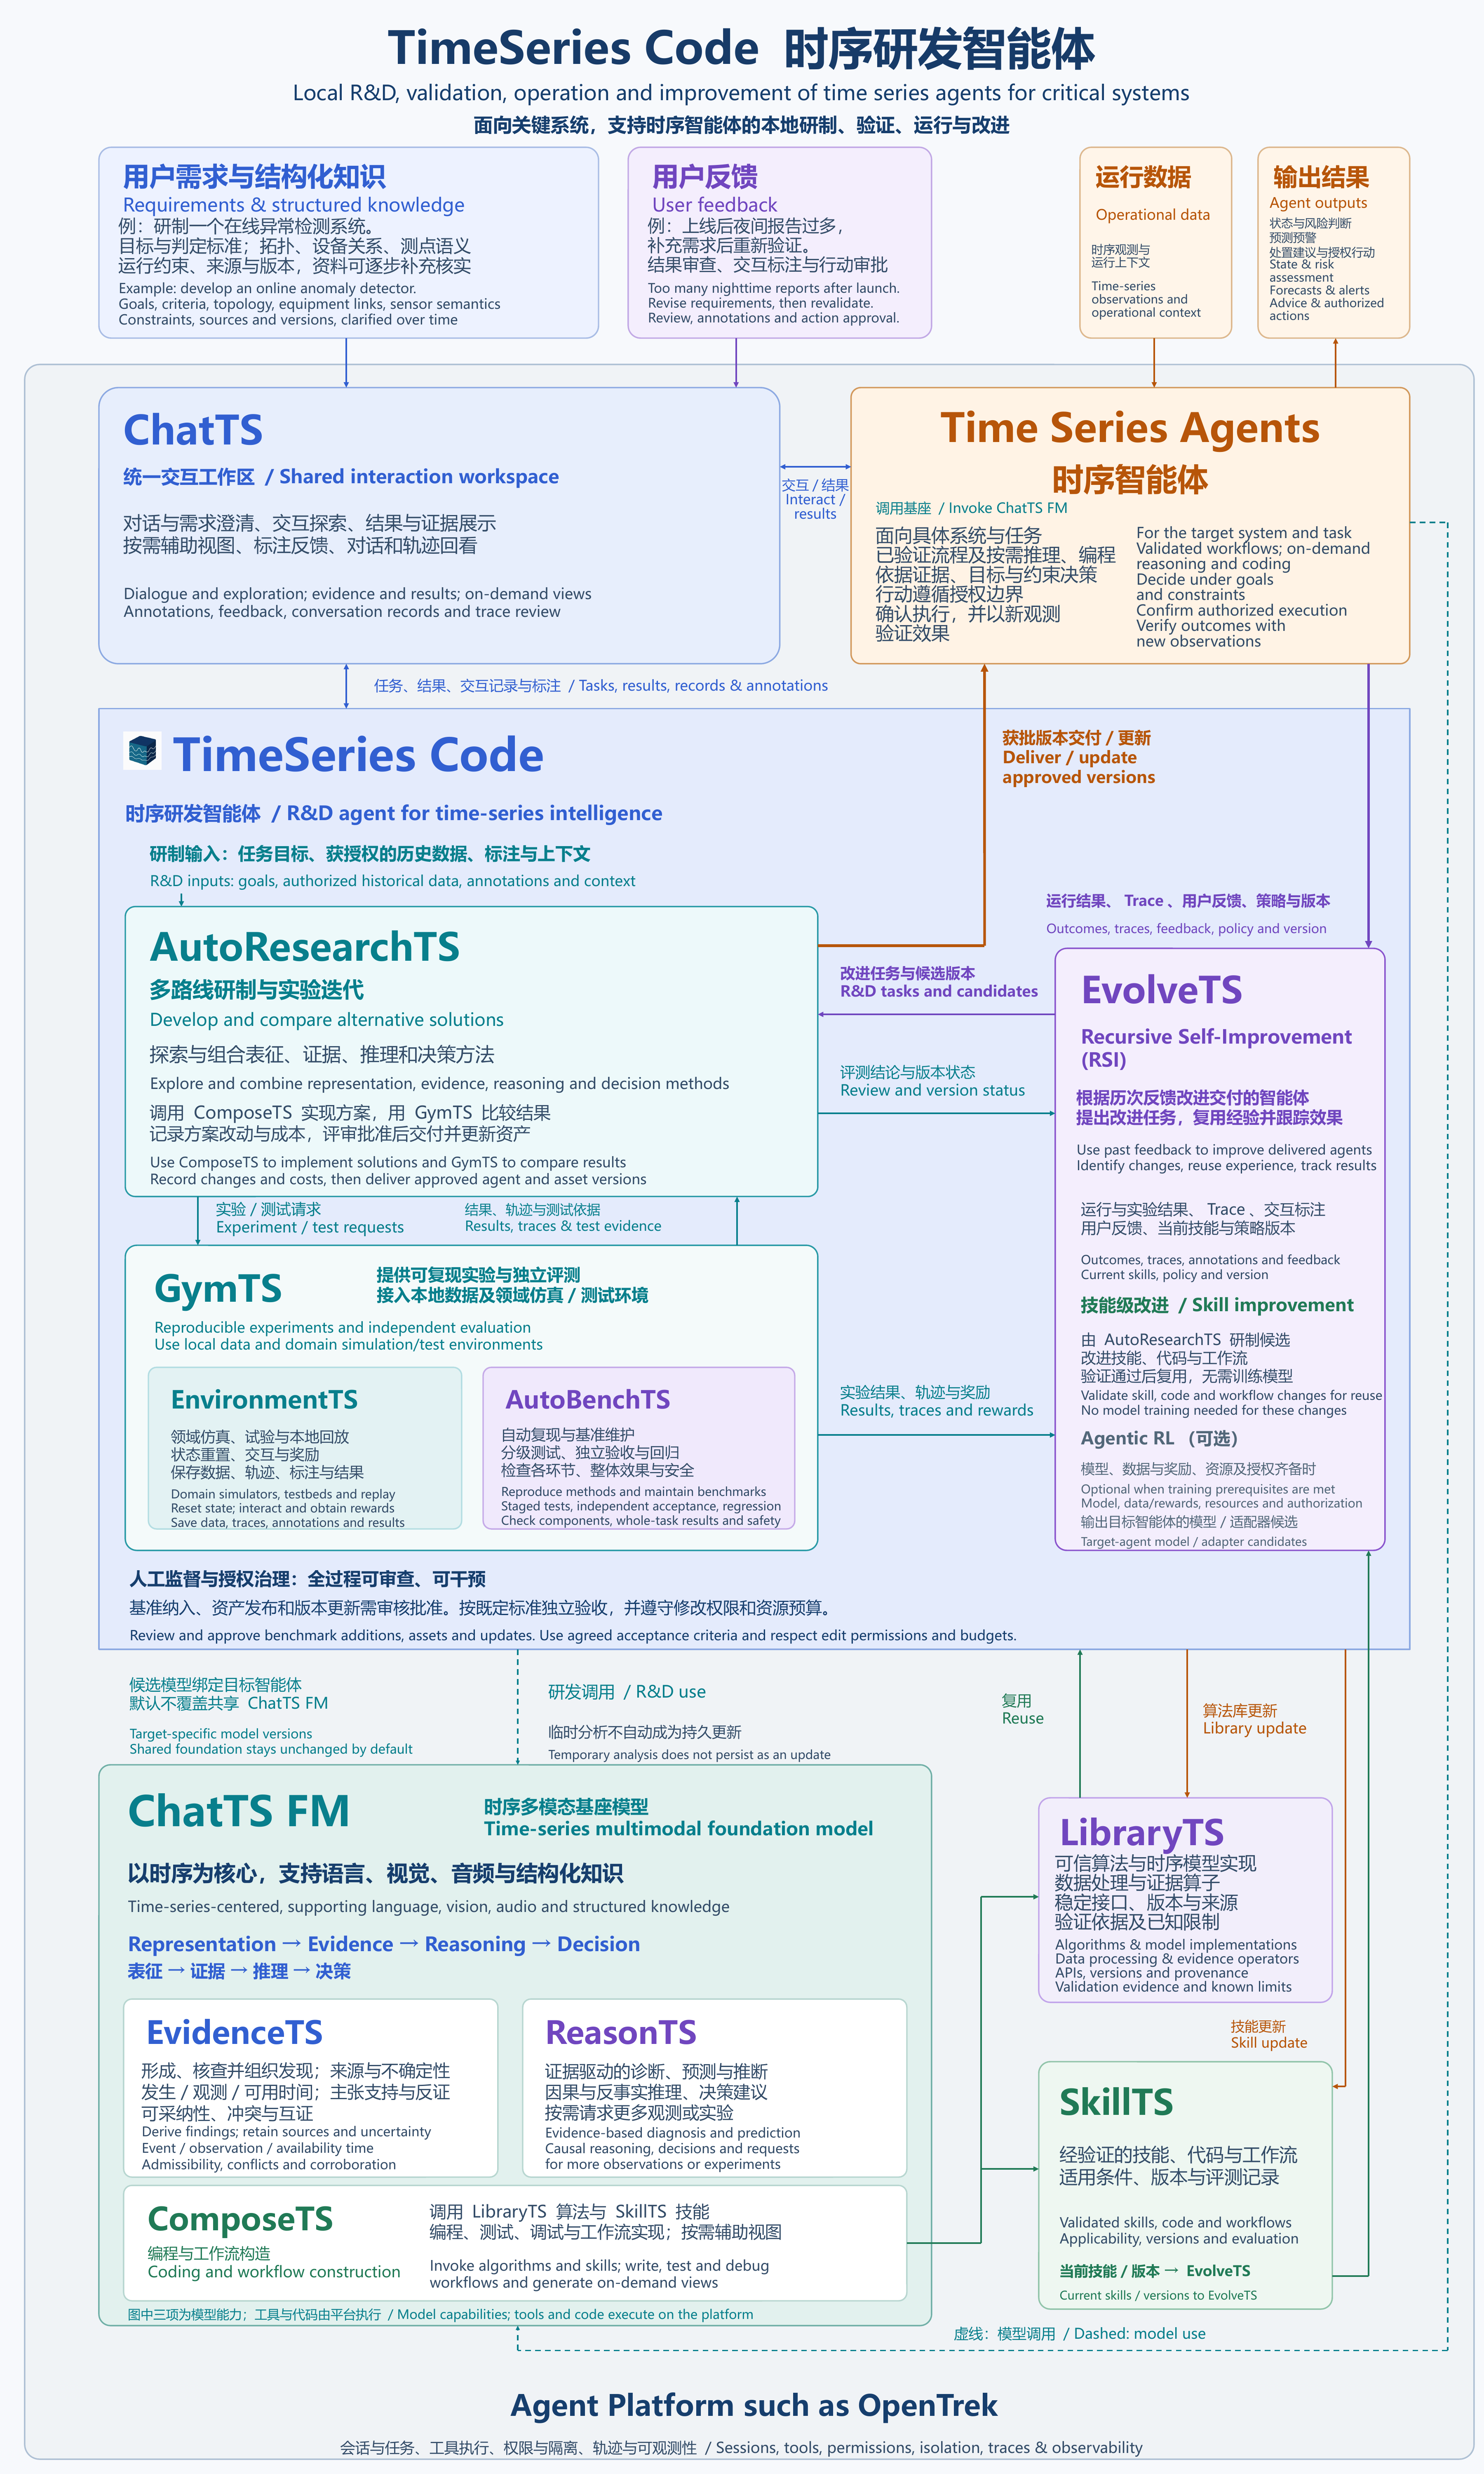
TimeSeries Code is the R&D agent. It helps develop, validate and improve Time Series Agents for particular systems and tasks, including anomaly detection, forecasting, diagnosis, and health and performance analysis. Both run on an Agent Platform such as OpenTrek. The platform can keep their processes, model instances and permissions separate where the task requires it.
ChatTS is the shared interaction workspace. Users bring requirements, available domain knowledge and feedback here. They can explore observations, inspect results and annotate findings. Topology, sensor meanings, operating constraints and acceptance criteria can be supplied and clarified over time. A task can request a particular plot or interactive view when it is needed. Conversation records and annotations remain available for later development.
There are four main interactions. User requirements and user feedback enter ChatTS separately. Operational data enter the delivered agents, which produce agent outputs such as state and risk assessments, forecasts, recommendations and authorized actions. Results can also be presented and discussed through ChatTS. Development can use authorized local observations and evidence as needed.
A shared foundation for development and operation
ChatTS FM is the shared time-series multimodal foundation model. It supports language, vision, audio and structured knowledge alongside time series. The model and its callable methods help represent observations while preserving the timing, identities, numerical scales and missingness needed for the task. Within this foundation, EvidenceTS forms, checks and organizes findings in relation to a claim. It retains support and counterevidence, provenance, uncertainty, event time, observation time and availability. It also checks whether information is admissible and whether findings conflict. ReasonTS uses the evidence to compare explanations and possible action consequences, and can request more observations or experiments. ComposeTS writes, tests and debugs code and workflows, using algorithms in LibraryTS and reusable skills in SkillTS. The agent platform executes the tools and code.
The R&D agent and operational agents share this model and these assets. An operational agent can investigate an unfamiliar situation, reason from additional evidence and generate code on demand within its authority. When it takes an authorized action, it needs to confirm execution and use new observations to check the actual effect. Incomplete evidence or an unexpected effect can prompt further investigation. Some agents provide assessments or advice without directly controlling equipment.
This investigation takes place within the current task. A persistent change to the deployed agent follows a separate development and approval process. EvolveTS identifies changes worth retaining across runs, arranges development and testing, and follows an approved version into operation to check whether it helped.
Three modules within TimeSeries Code
AutoResearchTS organizes development around a defined task. Using local data, knowledge, goals and constraints, it explores and combines methods for representation, evidence, reasoning and decision. It can retain alternative algorithms, pipelines or workflows, implement them through ComposeTS, and use GymTS to compare their results. The comparison considers task performance, stability and resource costs. For each candidate, it records what changed, which earlier version it came from, the data and environment used, the results and the cost. These records help decide which routes to continue, revise or stop. The search stays within an agreed modification scope and budget. AutoResearchTS also organizes review and delivery of approved versions. A small correction can take a short implementation-and-test path.
GymTS provides reproducible experiments and independent evaluation using local data and suitable domain environments. EnvironmentTS connects local history, traces and annotations to simulators, testbeds and replay environments. It provides interaction and reward interfaces and retains results and execution context. Where the environment supports it, saving and restoring experimental state lets candidates run under comparable conditions and helps reproduce a failure. We use suitable domain environments rather than assuming that we must build every industry’s simulator or testbed.
AutoBenchTS, within GymTS, supports automated reproduction, benchmark maintenance, regression and safety evaluation. It can start with inexpensive validity and leakage checks, then compare surviving candidates in larger experiments and different operating conditions. Tests can examine individual components and the task as a whole. Replay respects the information available when a decision was made, including relevant gaps and delays. Development tests guide the search. Final acceptance uses separate evidence and agreed criteria, with executable tests, domain constraints and held-out conditions where applicable. A model’s favorable assessment alone is insufficient for acceptance. Deployment still requires checks of actual operating results.
EvolveTS organizes recursive self-improvement of the delivered agents across runs. It uses operational outcomes, traces and feedback alongside current skills, policies and versions. Experiments from GymTS and review conclusions from AutoResearchTS provide further evidence. Analysis and coding reuse ChatTS FM. EvolveTS identifies improvement tasks, coordinates development and tracks the resulting updates in operation.
Skill-level improvement can change tool selection, evidence checks, algorithm combinations, task routing, failure recovery or stopping rules, as well as instructions, code and workflows. AutoResearchTS develops the candidate and GymTS tests it. This work does not require local model training. After validation and approval, EvolveTS retains reusable experience with its conditions of use and known limits. Later tasks can draw on that experience, while evaluation checks whether an update also weakens existing capabilities.
Agentic RL is optional. A suitable model, usable and authorized training data, reward signals, training resources and approval must all be available. Traces describe what happened during execution. Training also needs a defensible way to judge the quality of those executions. Any resulting model or adapter remains a candidate for the target agent until evaluation and approval. It does not replace the shared ChatTS FM by default.
LibraryTS provides trusted algorithms, model implementations, data-processing methods and evidence operators. It records applicability, input and output requirements, provenance, versions, validation evidence and known limitations. SkillTS holds reusable skills, code and workflows with their conditions of use, versions and evaluation records. Paper extraction, experiments and operational experience can produce candidates for these repositories. The relevant validation and approval come before publication as trusted assets. Failed attempts remain in the development history.
Human oversight and authorization apply across all three modules. Users can examine evidence, intervene and stop work. The process specifies what may be changed, which constraints must be preserved, and how much time or computing resource may be spent. Benchmark inclusion, asset releases and persistent agent updates require the appropriate review. Acceptance follows agreed criteria, which a candidate cannot loosen to improve its score. Releasing an asset version is separate from enabling it for a particular agent.
This loop runs in the user’s local environment. Local data and traces stay there by default. A lack of local training resources does not imply permission to send traces elsewhere for training. Skill and workflow improvements can still proceed. The improvement target here is the delivered Time Series Agents, separate from our development of the project’s general models and R&D system.
Open the high-resolution architecture diagram
Application domains
We organize this research around seven domains, using concrete systems to guide the development questions. These examples describe our research scope rather than a list of completed deployments.
- Information infrastructure: data centers, computing networks, communications, and navigation and timing facilities.
- Energy systems: power generation and storage, transmission and distribution, electricity use and control, oil and gas, heat supply, coal facilities, and hydrogen production, storage and transport.
- Transportation, aviation and aerospace: road and rail vehicles, ships and submarines, aircraft and engines, drones, spacecraft, satellite platforms, and supporting facilities and networks.
- Major industrial equipment and production facilities: lithography systems, advanced machine tools, equipment test benches, tunnel boring machines, and industrial production facilities.
- Major scientific facilities: research wind tunnels, propulsion testing facilities, fusion facilities, accelerators, light and neutron sources, and astronomical observatories.
- Environmental sensing and monitoring: robot sensing through RF, vibration and touch, weather radar, ocean sensing and sonar, and networks for weather, ocean, earthquake, air quality, water quality and geological safety monitoring.
- Water infrastructure and urban utility networks: reservoirs, dams, pumping stations, water supply and treatment, drainage, and underground utility networks.
Open the high-resolution application domains diagram
An example: developing an online anomaly detector
Consider an operations team that asks: “Develop an online anomaly detection system using our KPI data.” Through ChatTS, the team clarifies how results will be used, supplies available system knowledge and agrees on acceptance criteria. AutoResearchTS uses ChatTS FM and ComposeTS to develop alternatives, drawing on LibraryTS and SkillTS. GymTS runs comparable experiments, starting with inexpensive checks where possible. The candidates’ performance, changes and resource costs are recorded. The selected version is frozen before independent acceptance on held-out data. After review and authorization, it is delivered as a time series agent on the platform. A limited rollout checks how it behaves under actual operating conditions.
Suppose users then receive too many reports at night. A request to “stop reporting at night” needs clarification: the team may want to retain detection records while pausing routine notifications. Once the team confirms the requirement, EvolveTS uses it alongside the current version and operational evidence to define an improvement task. Applicable skills and earlier validated experience can help guide the next attempt. AutoResearchTS calls ComposeTS to revise the implementation and compares alternative reporting rules or detection methods where needed. GymTS provides replay, independent acceptance and regression tests. Review and approval precede an update to the target agent. Reporting volume and detection quality are evaluated separately, and subsequent operation shows whether the change helped without degrading other capabilities.
This illustrative case shows how requirements develop through use. The first release gives the team something concrete to evaluate. Feedback then leads to a defined change, new experiments and another approved version. We want TimeSeries Code to support that continuing work, so that users can develop methods locally and keep checking them as their systems and needs change.